Why direct calls to models destabilize the budget
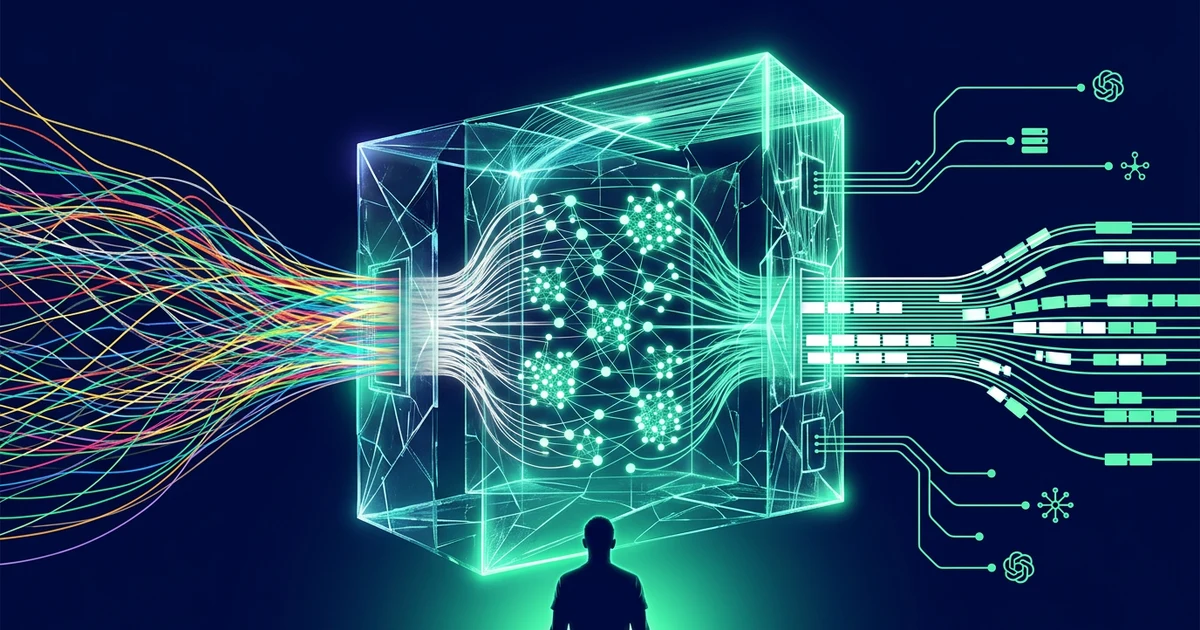
When multiple departments integrate foundation models in isolation, the organization loses visibility over the volume of consumed tokens and operational credentials. Each team configures its own access keys, exposing the company to unforeseen cost overruns when request traffic increases without centralized monitoring.
This technical dispersion fragments the AI technology stack, complicating security auditing and regulatory compliance. Without an intermediate mediation layer, service incidents at a commercial provider directly disrupt internal production systems.
The absence of a common control point also hinders the adoption of alternative models. If a company decides to migrate to lower-cost options or open weights, engineers must refactor the code of each connected service instead of adjusting a global routing rule.
Operational capabilities of an AI proxy architecture
An AI gateway operates as a specialized reverse proxy that interprets the semantic and economic features of artificial intelligence workloads. Unlike a traditional web traffic load balancer, this component analyzes token consumption and request content to make real-time engineering decisions.
| Architectural function | Technical mechanism | Operational impact |
|---|---|---|
| Semantic cache | Embeddings of previous queries to respond without inferring | 20% to 40% savings on recurring tokens |
| Failover | Automatic retry with backup models in case of API failure | Operational continuity without interface downtime |
| Cost-based routing | Routing simple tasks to compact models and complex ones to frontier models | Expense optimization without losing quality |
Semantic caching transforms the cost structure of recurring processes. By calculating vector similarity between a new query and already resolved transactions, the system returns existing results without paying for external inference or waiting for the original provider's latency.
In the project experience of D57 AI Solutions, the strategy and enterprise artificial intelligence implementation unit of Digital57, architectures that decouple business logic from inference interfaces accelerate value delivery. Application development time was reduced by more than 70% with AI-assisted construction workflows. This optimization occurs when developers interact with standardized services instead of dealing with individual provider integrations.
Application development time was reduced by more than 70% with AI-assisted construction workflows.
%
Criteria for evaluating and incorporating a gateway into production
Selecting this piece of infrastructure requires balancing internal latency requirements with corporate governance demands. There are open-source solutions deployable in private clouds as well as managed cloud platforms, each with specific technical trade-offs:
- Native support for multiple commercial model providers and local inference servers.
- Added latency from the interception layer of less than 25 milliseconds per processed request.
- Centralized audit logging with obfuscation of personal data before sending the payload to external networks.
- Configurable budget allocation mechanisms and automatic service cutoff by cost center.
Implementation begins by routing a single high-volume use case through the proxy. This proof of concept validates the semantic cache hit rate and delivers empirical savings data before requiring migration across other development teams.
Technical autonomy versus centralized team control
Deploying an infrastructure control point often creates tension between the agility developers seek and the rigidity operations teams fear. Product teams prefer to test the latest model versions without waiting for security approvals or procurement.
A proper AI gateway design resolves this friction by granting governed autonomy. The platform delivers virtual keys with assigned budgets and authorized model catalogs to each technical squad, eliminating the bureaucracy of manual requests without compromising the organization's financial visibility.
This institutional balance supports the enterprise AI implementation, transforming technical oversight into an enabler that protects operational stability rather than a bureaucratic bottleneck.
Frequently asked questions
How does an AI gateway differ from a standard enterprise API gateway?
A traditional proxy manages quotas by request volume and bandwidth in bytes. An AI gateway understands token structures, calculates semantic similarity metrics for caching, and applies load balancing based on the context window and specific inference costs.
What latency penalty does this intermediate layer introduce?
Modern solutions optimized in high-performance languages add a typical overhead of 10 to 20 milliseconds. This latency is negligible compared to the hundreds of milliseconds or seconds required for full token generation by external providers.
How does the gateway protect the privacy of corporate information?
The system intercepts the payload before it leaves externally, allowing the execution of filters to detect personal data or corporate secrets. Using regular expressions or lightweight local classifiers, the gateway masks sensitive information before completing the call to the model provider.
Conclusion
The AI gateway represents the indispensable control component to scale automation initiatives without risking budgets or exposing operational credentials. Centralizing routing, failover, and semantic caching allows companies to govern their technical consumption and maintain the flexibility to switch providers according to market evolution.
Content co-created with the help of artificial intelligence and the D57 strategy team.